Set up Pipelines
Configure publications, destinations, and Supabase Pipelines.
Public Alpha
Supabase Pipelines is currently in public alpha. Features and behavior may change as we continue developing the product.
Supabase Pipelines replicates Postgres data to a destination you configure in the Dashboard. Supabase runs the pipeline using the open-source Supabase ETL.
Initial sync copies existing rows from selected tables. Ongoing replication uses change data capture (CDC) to apply subsequent inserts, updates, deletes, and truncates.
Pipelines provides at-least-once delivery. How repeated changes affect stored data and query results depends on the destination. See delivery guarantees for destination behavior, ordering, and recovery limits.
Create a pipeline, then refer to settings, management, or advanced publication options as needed.
Before you start
Check the plan and project requirements and supported destinations.
Region
Managed Pipelines run in AWS eu-central-1 (Frankfurt), independently of your source and destination regions. This region is fixed. Choose nearby destination resources to reduce latency and replication lag.
Pricing
Pipelines charges for configured pipeline hours, initial sync data, and ongoing replication data. Destination-provider charges are separate. See rates, estimates, and billing examples.
Setup overview
The Dashboard is the supported way to enable Pipelines and create a managed pipeline. Prepare your destination before setup. To select the data to replicate, create a Postgres publication in the Dashboard during setup or create it with SQL ahead of time.
Step 1: Prepare your destination
Follow your destination guide to prepare its resources and credentials, and check its source table requirements:
Step 2: Enable Pipelines
Pipelines installs an etl schema and a database event trigger to track replication and schema changes. If your application already has an etl schema, rename it before enabling Pipelines. See what Pipelines installs and how to remove it.
- In the Dashboard, go to Database > Pipelines.
- Click Add pipeline.
- If Pipelines is disabled for the project, review the Enable Pipelines dialog and click Enable. The destination selection opens after you enable Pipelines.
Step 3: Configure a destination
For Publication, choose an existing publication or select New publication, name it, and add at least one table. For schema-wide replication or advanced publication options, create the publication with SQL. Under Initial sync, keep All tables to copy existing rows from every published table, or choose which tables to copy.
Destination form
- Select your destination. Enter a Pipeline name, set Publication and Initial sync, and enter the destination connection details from Step 1.
- If needed, use Advanced settings to change batching, initial sync concurrency, or slot recovery.
- Click Start pipeline to validate the configuration. Fix any blocking issues and run validation again. If only warnings remain, review them, click Start pipeline anyway, and confirm the warnings with Create and start pipeline anyway.
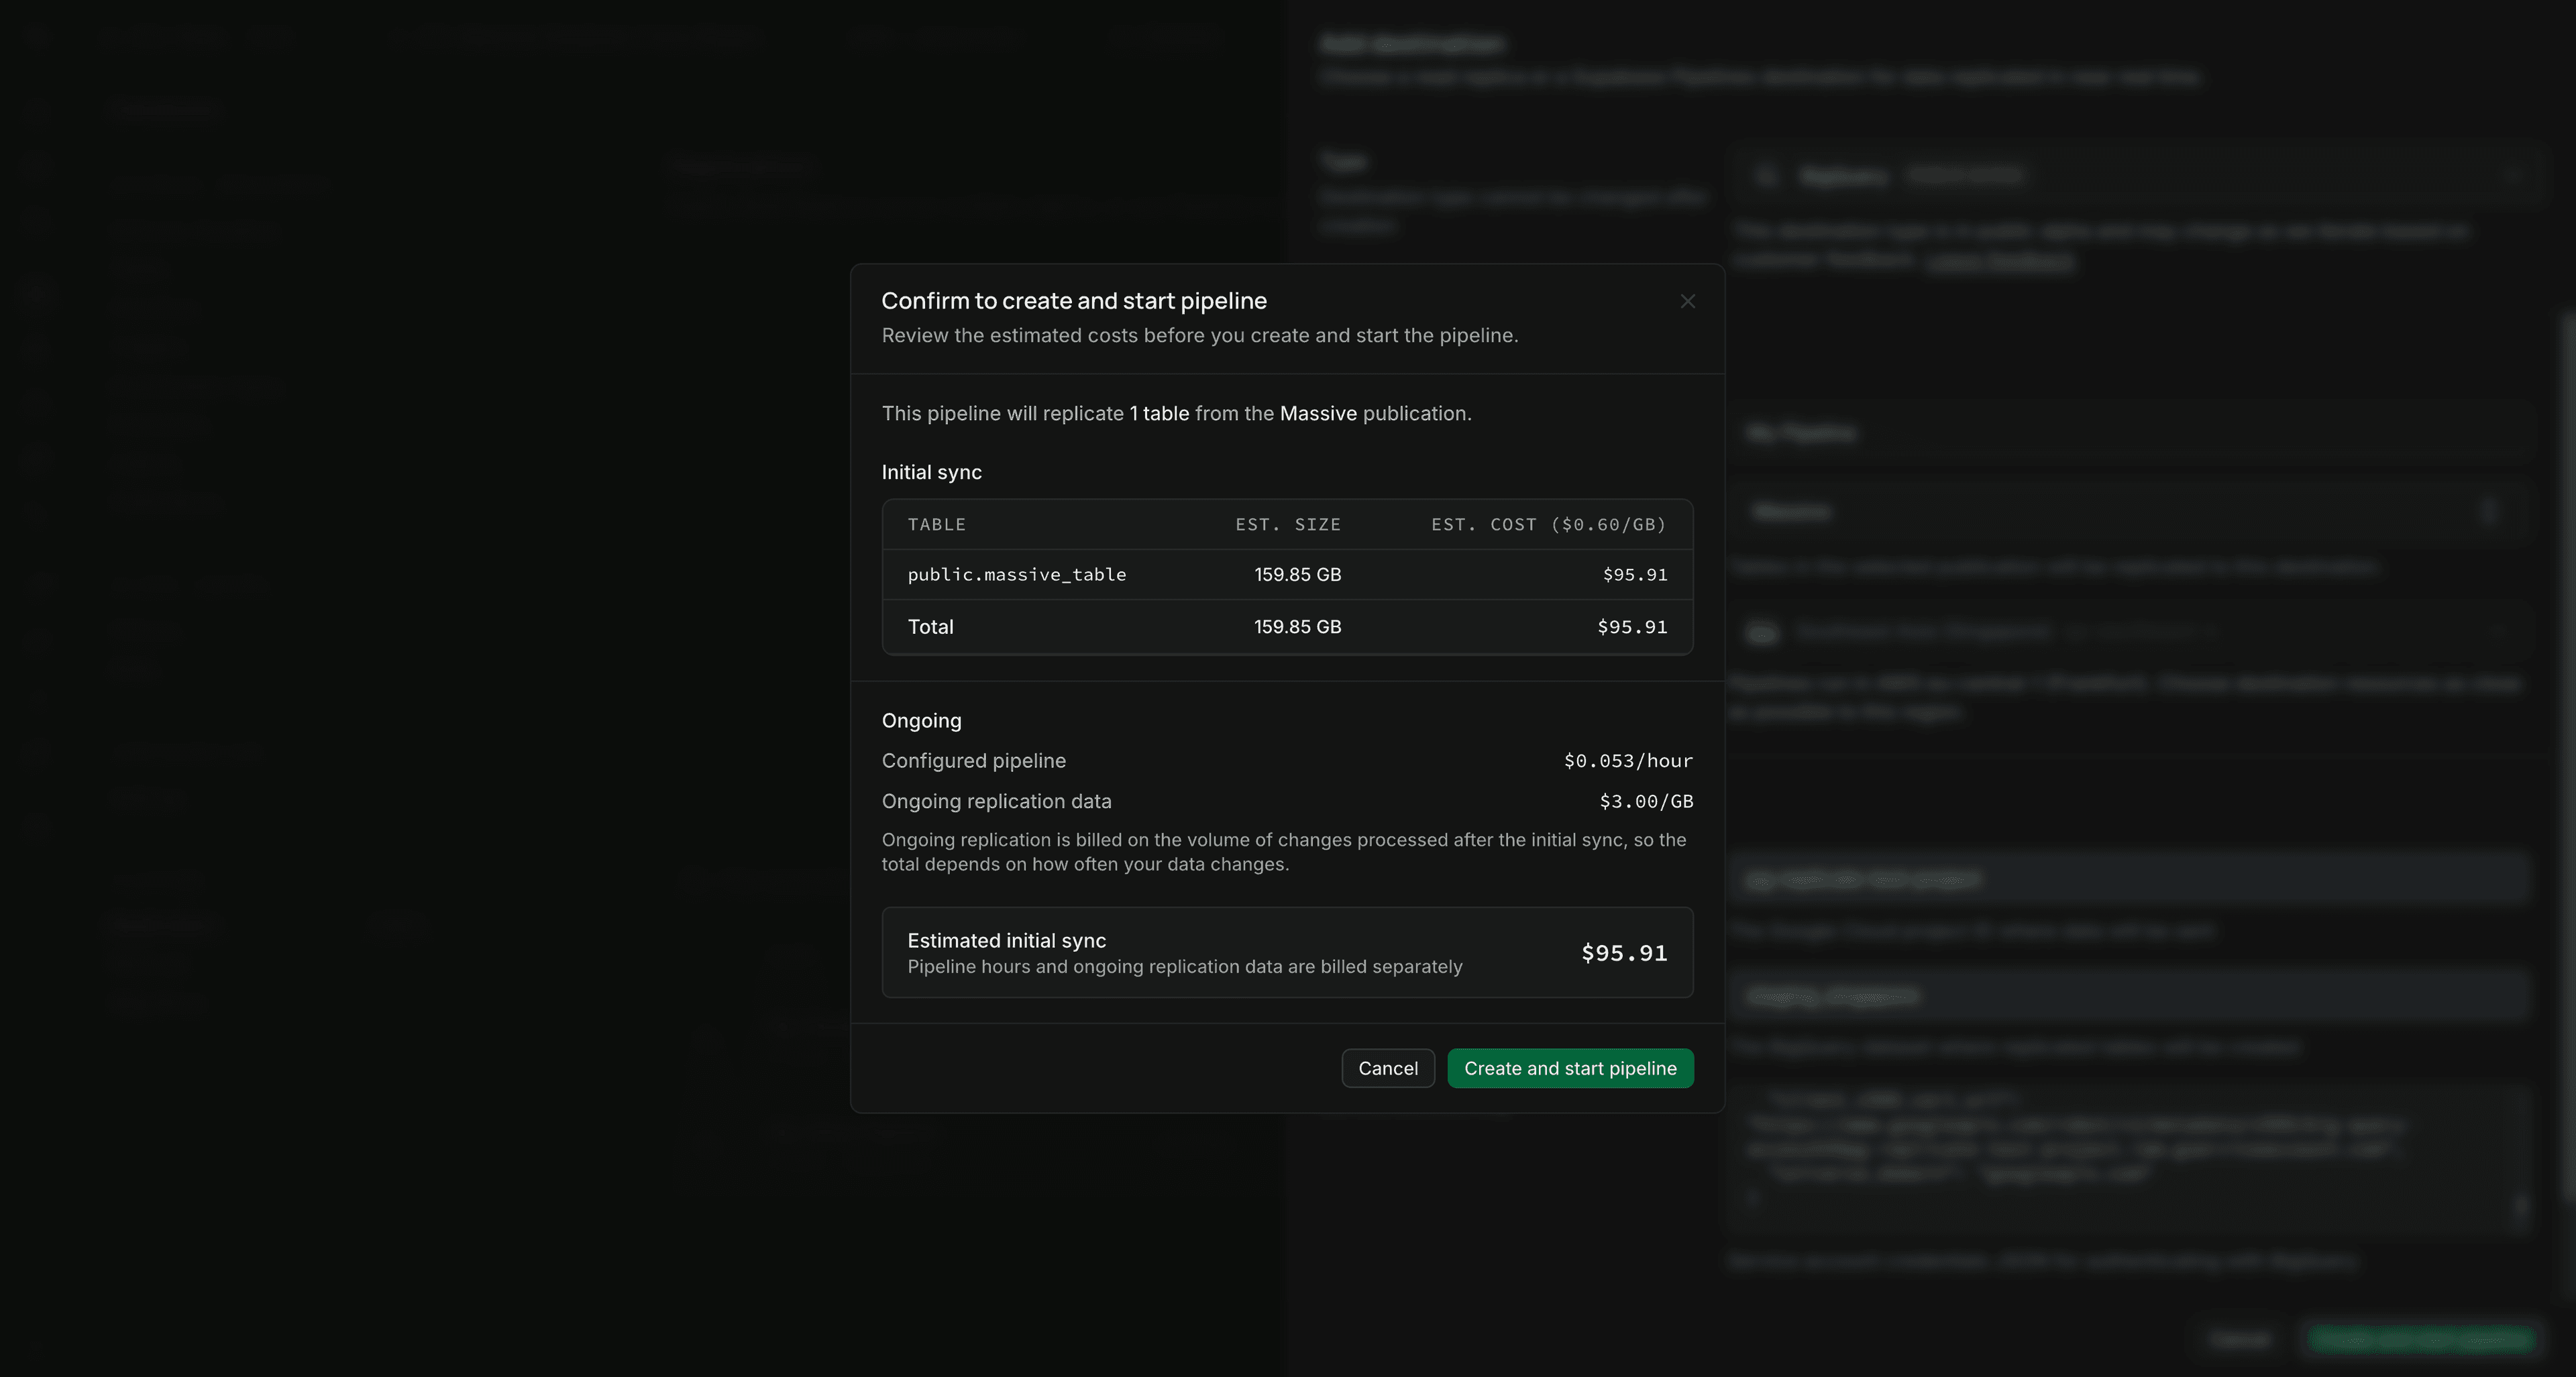
- Review the cost estimates and click Create and start pipeline in the cost dialog.
Pipeline creation wizard
- On Destination, select your destination and click Continue.
- On Connection, name the pipeline and enter the destination connection details from Step 1. Click Continue to validate the connection. If warnings appear, review them and click Continue again.
- On Data, set Publication and Initial sync. If needed, adjust advanced replication settings. Click Continue.
- On Review, check the configuration, estimated initial sync cost, and ongoing charges. Click Start pipeline to run final validation. Fix any blocking issues and run validation again. If only warnings remain, review them and click Start pipeline anyway.
The pipeline copies the selected tables' existing rows and begins ongoing replication for every published table.
Step 4: Monitor your pipeline
Open the pipeline and check that tables progress to Live and replication lag catches up. See pipeline states, metrics, and logs to assess progress and diagnose problems.
Pipeline settings
Review initial sync choices and creation checks before tuning advanced settings.
Choosing which tables to copy
Initial sync controls which publication tables copy their existing rows. Ongoing replication includes new changes from every published table.
| Selection | Existing rows copied |
|---|---|
| All tables | Every published table; the default |
| All except selected tables | Every published table except those you exclude |
| Selected tables only | Only the tables you include |
| No tables | None; replicate new changes only |
Selection changes affect unfinished initial syncs. To copy a completed table again, include it here, apply the settings, and reset the table.
Skipping initial sync does not preserve or attach to previously loaded destination data. A table reset erases destination data even when initial sync is skipped.
Creation checks
The Dashboard checks source access, logical replication settings and capacity, the publication, destination connectivity, and destination table requirements. Publications must contain at least one table and exclude the internal etl schema. FOR ALL TABLES is rejected.
A warning can recommend increasing max_slot_wal_keep_size so Postgres retains changes during initial sync. Higher retention uses more source storage; check available disk before applying the recommendation. See WAL configuration and monitoring.
Advanced settings
Leave these settings at their defaults unless you need to tune latency, initial sync speed, or recovery behavior.
| Setting | Behavior |
|---|---|
| Batch wait time | Default: 10000 milliseconds. Maximum wait after the first buffered row or change before flushing a partial batch. Size and memory limits can flush earlier. Accepts whole milliseconds from 0. |
| Table sync workers | Default: 4. Maximum tables copied concurrently. Each active worker uses an additional replication slot. Accepts whole numbers greater than 0. |
| Initial sync connections per table | Default: 4. Maximum source connections copying one table. Total connection use increases with both concurrency settings. Accepts whole numbers greater than 0. |
| Invalidated slot behavior | Default: Block startup, which requires manual recovery. Recreate slot rebuilds an invalid main slot and restarts replication for all tables from scratch on the next start. |
Lower batch wait times reduce batching delay; higher values can improve write efficiency. For concurrency tradeoffs, see Initial sync and table-sync slots.
Recreate slot replaces every destination table, including tables excluded from initial sync. Review lost-slot recovery before enabling it.
Managing your pipeline
Use the three-dot actions menu on a pipeline row:
- Start pipeline: Begin replication for a stopped pipeline
- Update available: Review and apply the latest managed pipeline version when an update is available
- Stop pipeline: Finish in-flight work and stop. Shutdown can take several minutes. WAL accumulates and pipeline-hour billing continues while stopped.
- Restart pipeline: Restart with the saved settings and replication progress. Required after adding or removing publication tables. Review the recovery behavior below before restarting during initial sync.
- Edit pipeline: Modify credentials, initial sync selection, or advanced options. Apply the changes and restart an active pipeline. If the pipeline was stopped, save the changes, then start it when ready.
- Delete pipeline: Delete the pipeline and stop replication. Already replicated data remains at the destination.
Viewing publications in the Dashboard
View publications and their tables in Database > Publications.
Adding or removing tables
FOR TABLES IN SCHEMA includes new tables automatically, but Pipelines discovers them only after a pipeline restart. To exclude an implicitly included table, change the publication scope or use an explicit table list; ALTER PUBLICATION ... DROP TABLE cannot exclude it.
These examples use the pub_users_orders publication from the SQL example. Replace it and the table names with your own; tables must already exist.
Adding tables to replication
-
Add existing source tables to your explicit table-list publication using SQL:
alter publication pub_users_ordersadd table products, categories; -
Review the initial sync selection for the added tables, then select Restart pipeline from the pipeline's actions menu.
Removing tables from replication
-
Remove the table from your Postgres publication using SQL:
alter publication pub_users_ordersdrop table orders, products; -
Select Restart pipeline from the pipeline's actions menu.
After the restart, Pipelines removes its replication state for those tables. Source tables and destination tables, including data already replicated, remain unchanged. Other pipelines using publications that still include the tables are unaffected. If multiple pipelines use the changed publication, restart each one.
You can delete the destination tables yourself after the restart. Don't modify or delete tables still managed by Pipelines; doing so can stop replication and require a table reset.
Pipeline restarts and recovery
A pipeline restart preserves saved progress for tables that completed initial sync. If the restart interrupts a table while copying or catching up after its copy, that table starts its entire initial sync again. Its partial destination data is deleted when it resumes. It does not resume from the last copied row or batch.
Resetting a table on an active pipeline restarts the pipeline, so other tables' unfinished initial syncs also start over. Use Reset table to deliberately rebuild a completed table. See restart and reset semantics.
If the main replication slot is lost and Recreate slot is enabled, startup rebuilds all replicated tables. Review lost-slot recovery for its data-loss and billing effects.
Disabling Pipelines
Delete all pipelines first. Then open the three-dot actions menu on the Pipelines page and click Disable Pipelines.
For cleanup details, see What happens when you disable Pipelines?.
Creating a publication with SQL
The following SQL examples assume you have users and orders tables with the referenced columns in your database. Schema-wide publications, column lists, and row filters require Postgres 15 or later. Choose one publication scope; the examples are alternatives.
Publication for specific tables
create publication pub_users_ordersfor table users, orders;This publication includes inserts, updates, deletes, and truncates for users and orders.
Publication for all tables in a schema
create publication pub_all_publicfor tables in schema public;This tracks changes for all existing and future tables in the public schema.
To include multiple application schemas, pass a comma-separated list. For example, if your tables are in public and analytics:
create publication pub_application_schemasfor tables in schema public, analytics;Both schemas must already exist. This includes their existing and future tables without including the internal etl schema. Restart the pipeline after adding new tables so it discovers them. See Postgres schema publications for syntax and requirements.
Publication for all tables
Pipelines rejects FOR ALL TABLES because it includes the internal etl tables. Replicating them can interfere with replication state. Use FOR TABLES IN SCHEMA for application schemas or list tables explicitly. Replace any existing FOR ALL TABLES publication; Postgres cannot narrow it in place.
Advanced publication options
Use these options to control which data is published and how partitioned tables appear at the destination.
Selecting specific columns
You can replicate only a subset of columns from a table:
create publication pub_users_subsetfor table users (id, email, created_at);For updates and deletes, a column list must include all replica identity columns. With REPLICA IDENTITY FULL, omit the list entirely. Postgres rejects source updates and deletes if a publication that sends those operations specifies a column list for the table, even if it names every column. Review the columns before removing a list because the publication can then replicate previously excluded columns. Also check your destination's source table requirements.
Filtering rows with a predicate
You can filter which rows to replicate using a WHERE clause. These examples copy matching existing rows during initial sync and then replicate matching inserts only:
-- Only replicate active userscreate publication pub_active_usersfor table userswhere (status = 'active')with (publish = 'insert');-- Only replicate recent orderscreate publication pub_recent_ordersfor table orderswhere (created_at > '2024-01-01')with (publish = 'insert');To also publish updates and deletes, every column used in the row filter must be covered by the table's replica identity. For example, REPLICA IDENTITY FULL covers all columns, at the cost of more WAL. Review Postgres row-filter restrictions and your destination's source table requirements before enabling those operations.
Postgres evaluates the filter before sending changes. A row matches only when the expression is true; false and NULL do not match. For an update, it checks both the old and new row:
| Old row matches | New row matches | Change sent to Pipelines |
|---|---|---|
| Yes | Yes | Update |
| No | Yes | Insert |
| Yes | No | Delete |
| No | No | No change |
This applies when updates are published. Row filters do not limit TRUNCATE: a published truncate affects the whole destination table. See Other publication changes before changing a filter on an existing pipeline.
Partitioned tables
publish_via_partition_root controls whether partition changes arrive as one parent table or separate leaf tables:
| Setting | Destination shape |
|---|---|
true | One table matching the published parent, including rows from its leaves |
false or unset in SQL | One table per replicated leaf |
| Publishing an individual leaf | One table for that leaf, regardless of this setting |
Schema-wide publications follow the same rule for partitioned tables; regular tables remain separate.
For example, if orders is partitioned by month:
-- Publish all partitions as the parent table.create publication pub_orders_rootfor table orderswith (publish_via_partition_root = true);-- Publish each leaf as a separate table.create publication pub_orders_leavesfor table orderswith (publish_via_partition_root = false);Publications created from the Dashboard replication flow default to publish_via_partition_root = true. Under Postgres partition handling, choose Replicate each partition separately to use false. If you create or alter a publication manually with SQL, set this option explicitly so the destination shape matches what you expect.
On Postgres 15 and later, row filters apply during both initial sync and ongoing replication:
- With
publish_via_partition_root = true, the published parent's filter and column list apply, even if a leaf has its own filter or column list. - With
false, each leaf's filter and column list apply. Define row filters on the leaves; Postgres rejects them on the partitioned parent in this mode.
See Postgres partition row filters for examples.
The publication setting controls which Postgres relation becomes a destination table. It does not copy the source table's physical partitioning configuration, partition key, or partition bounds to the destination.
Choose the mode before starting replication:
- With
true, new changes in a newly created or attached partition flow through the already tracked parent without a restart. Attaching a partition does not copy rows that were already in it. - With
false, a new leaf partition has its own table identity. Restart the pipeline to discover it; its existing rows are copied only if it is selected for initial sync.
To change modes, stop the pipeline, change the option, review Initial sync for the new table identities, then restart. Pipelines removes state for untracked tables and discovers new ones, copying existing rows only if selected for initial sync. Old destination tables remain; their data is not merged or split automatically.
With publish_via_partition_root = true, truncating a leaf partition keeps destination rows; truncating the published parent clears them.
A table reset discards retained rows. It copies current source data again only if the table is selected for initial sync.
Other publication changes
Publication changes do not all require a pipeline restart:
| Change | When it takes effect |
|---|---|
| Add or remove published columns on an already tracked table | Applied while the pipeline runs, subject to the destination's schema-change restrictions. |
| Change a row filter | Postgres applies the new filter to ongoing changes without a pipeline restart. |
Change published operations (insert, update, delete, truncate) | Postgres changes which operations it sends without a pipeline restart. Previously omitted operations are not replayed. |
Change publish_via_partition_root | Stop the pipeline before changing this option, then restart it to discover the new table identities. See Partitioned tables. |
Removing a published column also removes its destination values. Including it again does not restore the removed values automatically. This applies across destinations. A table reset copies current source values again when the column is published and the table is selected for initial sync.
Changing a row filter affects future changes only: it neither copies newly included historical rows nor removes rows that no longer match. For tables that completed initial sync, a pipeline restart does not rebuild history. To rebuild it, include affected tables in initial sync and reset those tables.
Wait for initial sync to finish before changing its filter; changing a filter does not update a copy already in progress.
ALTER PUBLICATION ... SET TABLE replaces the table list. When changing column lists or filters, include every table you want to keep; omitted tables are removed.
Schema change support
Pipelines applies supported changes to replicated columns as replication progresses. It does not mirror every Postgres DDL operation. Check the supported changes and destination behavior for BigQuery, ClickHouse, DuckLake, or Snowflake before altering replicated tables.
Run schema migrations one at a time in short, fresh READ COMMITTED transactions. Avoid concurrent schema changes to related tables, types, or publications.
Unsupported changes have different outcomes:
- Data type changes do not migrate existing destination columns. BigQuery, DuckLake, and Snowflake generally skip type changes with a warning. ClickHouse rejects changes that alter its mapped type or timestamp semantics; see its type-change rules. Keeping the old destination type can cause later values to be rejected or interpreted differently.
- Unsupported defaults and tightening
NOT NULLare skipped with a warning. Replication can continue with a different default or a more permissive destination column. Each destination guide describes these differences; skipping a default does not skip the values Postgres supplies in row changes. - Incompatible schema changes are rejected with an error, such as changing the primary-key definition used by BigQuery or ClickHouse's
ReplacingMergeTree. Failed or interrupted schema changes can require manual recovery.
Check replication logs for warnings and errors after changing a replicated table.
Some schema and publication changes require a table reset. A reset rebuilds the destination schema and deletes existing destination data. Resolve any source incompatibility before resetting. To copy current source rows again, select the tables for Initial sync and apply the settings before resetting. Restarting the pipeline alone does not rebuild tables that completed initial sync. Do not repair managed destination objects manually.
Limitations
Pipelines has the following limitations:
- Source tables: Primary-key, replica-identity, and publication-column requirements depend on the destination. See its destination guide before creating the pipeline.
- Transformations: Pipelines maps names and types for the destination but does not run user-defined transformations.
- Custom data types: Custom values replicate as strings. Check that your destination can interpret those string values correctly.
- Arrays: Only one-dimensional arrays are supported. Non-default lower bounds are not preserved. Check the destination guide for additional array restrictions.
- JSON nesting: Source
jsonandjsonbvalues can have up to 127 levels of nested objects and arrays, including the outermost object or array. The limit also applies to each JSON value in a Postgres array. Pipelines rejects deeper values while reading from the source. - Generated columns: Generated columns are skipped. Use triggers to store derived values in regular columns if you need them in the destination.
Destination-specific limitations, such as row size and type mappings, are documented in each destination guide.